Trace with Built-In Traces
You can trace your pipelines through built-in traces in the UI. Traces give you full observability into your deployed pipelines and agents without adding a separate observability tool to your stack: everything stays on the same infrastructure your pipelines already run on.
For more advanced use cases, use the deepset MCP server to interact with traces and other resources. For details, see Using deepset MCP Server.
About This Task
Traces require no setup. As soon as you deploy or redeploy a pipeline, it starts generating traces automatically for every run.
To learn more about traces, see Monitor Pipeline Performance and Trace Your Pipelines.
Traces are collected for queries run on or after 25 June 2026. Before that date, traces are not available. To collect traces for pipelines deployed before that date, undeploy the pipeline and deploy it again.
What a Trace Captures
A trace is the complete execution record of one pipeline run, from the input that triggered it to the response it returned. Each trace captures:
- Spans: A hierarchical tree of every component that ran, with per-step timing, component type, and metadata tags.
- Token usage: Prompt, completion, reasoning, and cache tokens, normalized across providers and attributed to the model that used them. This lets you compare token consumption across models even when an agent uses more than one. Cache tokens are split into cache reads and cache writes. To see how much of your cache spend comes from 1-hour cache writes, which Anthropic bills higher than its default 5-minute cache writes, check Cache write (1 hour) in the token breakdown. It's shown for providers that report it, such as Anthropic, and the cache write total includes these writes. The row shows a dash when the provider doesn't report the split.To set the price used for 1-hour cache writes, see Set Model Prices.
- Inputs and outputs: The data flowing into and out of every component.
- Logs: Every structured log entry from the run, with its level and source.
- Failures: The exception type, message, and full stack trace, with the root-cause component flagged so you know where the run failed and whether it's a configuration error you need to fix, or an external provider or infrastructure error that just needs a rerun.
- Metadata: Status, total duration, timestamps, the source that triggered the run (Playground, Builder, API, or a shared prototype), and the pipeline version that served it.
Trace Data Retention
Haystack traces stored with your search history are kept for a limited time. Each organization has a trace retention period, in days, that controls how long trace data stays available. You can see the current value in the trace_retention_period_days field returned by the /me endpoint. If your organization needs a different retention period, contact your deepset representative.
When a trace passes its retention period, it goes through two stages:
- Soft delete: The trace is marked as expired. It's automatically excluded from the search history list, and requests for that query's trace detail or trace payload no longer return trace data, even though the underlying search history entry and record still exist.
- Permanent delete: After a grace period following the soft delete, the trace artifact itself is permanently removed from storage. The search history entry stays in place, but the trace data it pointed to is deleted for good.
This process runs automatically in the background, so you don't need to take any action. Keep in mind that once a trace's retention period elapses, you can no longer view it in the search history or use it for debugging — plan on exporting or analyzing traces you need to keep before they expire.
View Traces
- Log in to Haystack Enterprise Platform.
- Click Pipelines, find the pipelines whose traces you want to see, and click Analytics next to it.
- Open Traces. You can see a list of all traces for the pipeline, each with its input, status, source, duration, total tokens, and date and time. Each trace represents the full journey of a single request as it moves through the pipeline.
Filter traces by status, duration, source, or date range to narrow down the list to a release window or a specific day. Sort by duration to find the slowest runs, or search by trace ID or input text to find a specific run, for example, one a customer reported. Select All in the source filter to clear the source constraint and show traces from every source.
View Trace Details
- On the Traces page, click a trace to open its details. Use the filters to find the traces you want to check.
- Click any trace to open its details:
- Use the top of the page to check the key information about the trace, including the pipeline version, status, source, root cause components, and more. If the run replayed an earlier session, a Replayed tag appears next to the status.
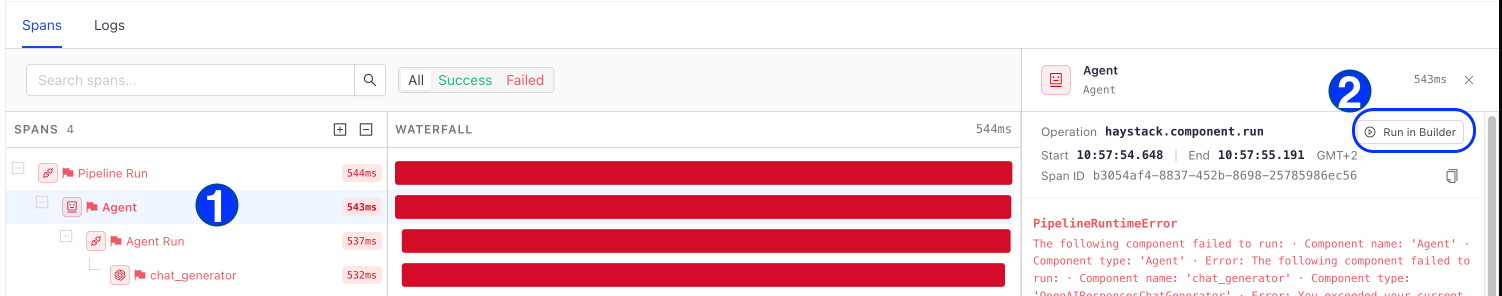
- Use the Spans section to see a hierarchical tree of all spans in the trace. You can search spans by name and filter by status. The Waterfall panel shows a timeline of all spans in the trace. You can see the start and end time of each span, and the duration of each span. Click a span to select it and see its details. Expand or collapse a span to see its children or parents.
- Use the Logs section to see the logs related to the selected span or the overall trace.
- If the trace is associated with a search session, a Session Files tab appears. Open it to browse every file created during that session: click a
.txt,.json,.yaml, or.ymlfile to preview it in a read-only code editor, or download any file directly from the list or the preview.
Drill into any component to see which one took the longest or consumed the most tokens. When a run fails, the trace names the root-cause component and shows whether the failure was a configuration error you need to fix, or an external provider or infrastructure error that you can typically resolve with a rerun.
You can use Fix with AI to fix failed traces with an AI assistant.
Investigate a Degraded Run
To spot runs that need attention, even ones that returned an answer, check the run status in the History tab of a pipeline's Analytics. Each run has one of these statuses:
success: The run returned a result and no component in its trace raised an error.degraded: The run returned a result, but at least one component in its trace raised an error that was caught further up the pipeline. Part of the run didn't work as intended, so check it.failed: The run ended with an error and didn't return a result.
To find out why a run is degraded, open its trace, go to the Spans section, and filter spans by status to find the component that raised the error. Then open the span to see the error details and the related logs.
Runs recorded before the degraded status was introduced keep their original status.
ToolInvocationError, and the run is degraded even though the Agent recovered and returned an answer. This way, you can spot tool failures that would otherwise be hidden behind a successful answer. The span's error message contains the error the tool returned. If content tracing is off, the message is Tool '<name>' failed, where <name> is the name of the tool. This applies to pipelines that use Haystack 3.4.0 or later. Runs on earlier Haystack versions don't mark failed tool calls as errors.Find a Failed Tool Call in a Trace
If an Agent returned an answer but a tool it called failed, find the failed call to see why it failed.
- In Haystack Enterprise Platform, go to Pipelines, open the pipeline, and go to Analytics > Traces.
- Open the trace of the run. A tool failure that the Agent recovered from shows a successful trace with an errored span.
- In the Spans section, filter spans by status to show the errored spans. The failed tool call appears as a root-cause span.
- Click the span to see its error type,
ToolInvocationError, and the error message from the tool.
The error message tells you whether the tool received wrong arguments, hit a timeout, or failed for another reason, so you know whether to fix the tool configuration or rerun the request.
A trace has its own status, success or failed, so a degraded run can show a successful trace with an errored span.
Run a Component from a Trace
If a component failed or produced unexpected results in a recorded trace, you can open it directly in Builder and re-run it with the original trace input. This lets you reproduce a specific run, experiment with different inputs, and debug issues.
- In Haystack Enterprise Platform, go to Pipelines and open a pipeline.
- Go to Analytics > Traces and open a trace.
- In the trace detail view, open the span for the component you want to investigate. If the trace contains a failed component, the failed span is selected automatically.
- Click Run in Builder on the span.
The Builder opens and the component run widget appears.
- Click Fill input from trace to run the component with the input recorded in the trace and click Run Component.
- To restore the original trace input at any time, click Fill input from trace in the widget.
- To go back to the trace and re-select the component, click Back to trace.
While you're working in Builder with a trace as context, you're in the inspecting a trace mode. To stop the trace session and return to normal Builder mode, close the inspecting trace indicator.
Capture an Indexing Trace When Reindexing a File
To debug indexing results, capture an indexing trace: it shows how a file was converted and split. Unlike query pipelines, an index records a trace only when you ask for one while reindexing a single file with the REST API. For instructions, see Capture an Indexing Trace with the REST API.
To see the traces of an index in the UI, open the index and click the Traces tab.
Evaluate a Conversation from a Trace
If you want to check how well a conversation performs against your quality criteria, you can judge it with one of the pipeline's Experiments without leaving the trace. The run always covers the whole conversation, with every turn judged, not just the trace you opened.
- In Haystack Enterprise Platform, go to Pipelines and open a pipeline.
- Go to Analytics > Traces and open a trace from the conversation you want to evaluate.
- Click Evaluate this conversation in the trace detail header.
- In the Evaluation tab that opens, select the Experiment you want to run.
- Click Run on this conversation to start the run. While it runs, the tab shows that it's judging the conversation. When it finishes, the results appear in the tab.
A run started from a trace is hand-picked, so it doesn't affect your Experiment's trends. It stays in the Experiment's history so you can find it later.
The run judges the trace's conversation if the trace belongs to a chat, or the trace's own query if it doesn't.
Reading the Results
The Evaluation tab lists every run that has judged the conversation, grouped by Experiment, with the newest run of each Experiment open. Open an older run to read its results. Each run shows:
- Metrics scoped to the whole conversation come first.
- Rows for each turn follow, at the turn's address (for example,
turn/3), in the order the pipeline run produced them. - Rationales and any reasons a Metric couldn't be scored (N/A) show inline with the result.
- Cells for Metrics that errored or didn't finish show their status the same way they do elsewhere in Evaluation.
If a cell errored because the LLM judge didn't conclude, the judge read the conversation but never sent a valid report. This isn't a problem with your pipeline. To fix it, see Fix Sessions Where the Judge Didn't Conclude.
If your organization already has many results being judged, this run waits in a queue before it starts. Temporary failures, such as a rate-limited LLM judge, are retried automatically. A run that waits more than 6 hours ends as failed. For details, see Runs Waiting for Capacity and Transient Failures. If an Experiment has no Metrics that apply to the conversation, the tab says so. Older runs that were focused on a single turn still appear and show only the rows they have.
Opening the Run in the Experiment
Click Open in Experiment to go to the Experiment's detail page with this run already selected, so you can share the diagnosis with a link or dig into it alongside the Experiment's other runs.
Results stay on the page only while it's open. To find them later, use the Open in Experiment link, or open the turn from its conversation in Evaluation: the turn panel lists every run that judged that conversation. For details, see Pipeline Evaluation.
If the pipeline has no Experiments yet, the tab links you to the Experiments section so you can create one first. For instructions, see Create an Experiment.
Investigate Traces with a Coding Agent
If you're debugging from your IDE, or need to sift through dozens of runs at once, point a coding agent at your traces through the deepset MCP server instead of reviewing them one by one in the UI. The MCP server lets your agent list and read traces, including logs and span tags, so it can look for patterns across many runs at scale. For details, see Using deepset MCP Server.
Navigate Between Traces and Search History
On the Traces page, next to a trace, click More Actions > View in History. This switches to the History tab within Analytics and keeps you on the same page, with the trace's query already selected.
You can also navigate between traces and Search History: jump from a trace to its Search History entry, or open the Trace Detail page directly from a query's detailed view in Search History.
To open the trace for a query you just ran in Playground or Prompt Explorer, click the View trace (bug) icon below the answer. Traces can take a few seconds to appear after a query.
Compare Traces
Every change you make to a pipeline, like a different model or a reworked prompt, might improve your output, but it can also change what the pipeline costs to run and how it behaves. Use Compare to weigh that trade-off instead of guessing at it.
Compare two traces side by side to see exactly what changed: how duration and token consumption moved at each component, and how the answer itself changed, with differences highlighted.
For example, if you swap in a larger generation model, Compare shows you what it cost: added duration and tokens at the generation step, while the rest of the pipeline holds steady.
You can also use Compare to catch regressions you didn't intend. Run the same input against a past pipeline version and the current one. If a component slowed down or started returning something different, you'll see it before your users do.
To compare two pipeline versions across many test cases instead of two traces, compare the versions in an Experiment. For details, see Compare Two Pipeline Versions.
- On the Traces page, enable Compare.
- Choose up to two traces to compare. Compare works well when you run the same input against two different pipeline versions.
- Choose a component from the pipeline run section to compare its inputs and outputs, duration, and token consumption for each trace.
Export Traces as JSON
You can export a trace as JSON either directly from the Traces list or from an open trace's detail page.
- On the Traces page, next to a trace, click More Actions > Export as JSON.
- Or open a trace from the Traces page and click More Actions > Export as JSON.
Data Security
Traces are stored on deepset-owned infrastructure, so trace data is never shipped to an outside observability tool. Access is scoped to each workspace with role-based controls, and data is encrypted at rest. You can export any trace as JSON whenever you need it.
Related Information
Was this page helpful?